cognitive load Archives | Shufrans TechDocs Home // cognitive load Archives | Shufrans TechDocs

Why Structured Language Outperforms AI Guesswork

Why Structured Language Outperforms AI Guesswork

Every time a new AI tool hits the market, the conversation shifts to what software can automate. We talk about translation speeds, draft generation, and automated summaries. We rarely talk about what happens when you feed messy, ambiguous documentation into a machine and let it scale your worst habits across every market you serve.

In sectors where a single maintenance error can shut down an entire rail network or ground a fleet, the challenge is no longer about generating more content. It is about control.

The Automation Trap

Organisations rushing to digitise legacy manuals or deploy automated translation workflows often assume technology will fix messy writing on the fly.

It does the exact opposite.

Generative tools amplify whatever they are given. If your source text is bloated, contradictory, or packed with local jargon, an AI model or machine translation engine will faithfully reproduce those flaws at scale, turning minor linguistic slips into systemic operational risks. When procedures span multiple languages and cross-border engineering teams, ambiguity is not just poor style, it is a financial and operational liability.

Why Structured Language Outperforms AI Guesswork

Engineering is deterministic. A technician on a shop floor or a mining site does not need a probable interpretation of a maintenance procedure. They need absolute clarity.

Controlling how technical information is authored solves this at the root:

  • Machine Readiness: Clean, rule-based source text is the only reliable foundation for AI training and automated localisation.
  • Zero Cognitive Load: Global teams and non-native speakers execute complex assembly and troubleshooting tasks faster when instructions leave zero room for guesswork.
  • Risk Mitigation: Standardised authoring rules eliminate the vague phrasing that causes costly downtime, equipment damage, and compliance failures.

Training for the Age of AI

Software cannot take legal liability for a failed maintenance procedure. The technical writers, engineers, instructional designers, and editors who govern your documentation remain the critical gatekeepers of your bottom line.

If your teams are building out AI workflows without first tightening the quality of their source communication, you are simply automating errors. Investing in structured language training for engineers, writers, and translators ensures your operations stay resilient, compliant, and profitable in an automated world.

Are your teams relying on AI to fix bad documentation, or are you building the linguistic standards required to make automation actually work? Let’s discuss how targeted training can future-proof your operations.

🔗 Reserve a 30-min STE Feasibility Session: https://calendly.com/shufranstechdocs/30min

At Shufrans TechDocs, we help aerospace leaders secure total linguistic control over their operations. We move beyond passive software tools by providing expert, human-centric STE training and implementation programmes tailored directly to engineering teams. By standardising technical data at the source, we remove ambiguity to ensure your documentation is accurate for human operators, readable for automated systems, and fully compliant with global safety standards.

To learn how to eliminate ambiguity from your technical documentation and protect your operational timelines, connect with the team at Shufrans TechDocs.


9 Years Later, a Slice of Cream Cake, and Why ‘Good Enough’ English is a Universal Cognitive Tax

9 Years Later, a Slice of Cream Cake, and Why ‘Good Enough’ English is a Universal Cognitive Tax

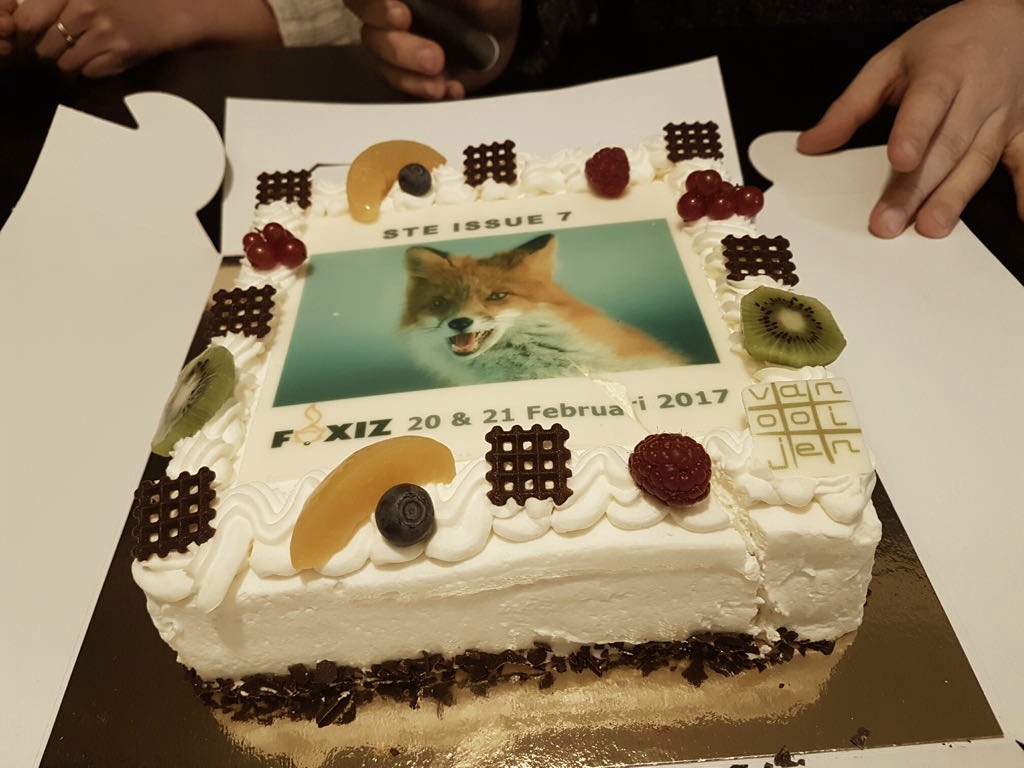
Shufrans TechDocs is currently marking a significant milestone as our principal trainer has reached 20 years of delivering technical documentation expertise and training to high-compliance industries. Such milestones prompt reflection on the evolution of linguistic standards. A retrospective look at our archives brought us to a few photographs from February 2017, taken during our ASD-STE100 Simplified Technical English training in Tiel, Holland.

During that session, our team and the participants celebrated the release of STE Issue 7 with a traditional cream cake. Beyond the rigorous application of controlled language rules, our trainer also hosted a traditional tea ceremony to provide a structured intermission from the technical material. These images highlight a persistent challenge, particularly the ongoing friction that technical authors and editors encounter daily when advocating for corporate linguistic governance.

A recent post-implementation review of our 2017 masterclass cohort confirms that a pervasive structural bottleneck remains unaddressed in web governance and software deployment documentation.

Modern software teams frequently use automated systems to extract user documentation directly from source code or system configurations. This process is efficient on paper. However, automated outputs that bypass rule-based linguistic standards consistently default to unstructured, traditional, and ambiguous prose.

When editors attempt to standardise this text to comply with ASD-STE100 guidelines during peer review, engineering teams often resist. Their argument is predictable: the wording is acceptable because the basic grammar is correct.

For technical communicators and developers managing this friction across globally distributed networks, the following arguments establish the objective business case for controlled language.


A recent post-implementation review of our 2017 masterclass cohort confirms that a pervasive structural bottleneck remains unaddressed in web governance and software deployment documentation.

Modern software teams frequently use automated systems to extract user documentation directly from source code or system configurations. This process is efficient on paper. However, automated outputs that bypass rule-based linguistic standards consistently default to unstructured, traditional, and ambiguous prose.

When editors attempt to standardise this text to comply with ASD-STE100 guidelines during peer review, engineering teams often resist. Their argument is predictable: the wording is acceptable because the basic grammar is correct.

For technical communicators and developers managing this friction across globally distributed networks, the following arguments establish the objective business case for controlled language.

The Reality of the Accessibility Card

Organisations routinely categorise web governance and documentation accessibility as an isolated compliance box, viewing it as a secondary accommodation for users with specific cognitive or physical challenges.

Shufrans TechDocs treats accessibility as a core functional requirement. Ambiguous text imposes a universal cognitive tax on all readers. Whether the user is a native speaker, an international client using English as a second language, or a systems engineer troubleshooting a critical failure under operational pressure, unstructured language forces the human brain to expend extra processing capacity simply to decode intent.

When technical content includes subjective attributes like “appropriate” or “sufficient” or relies on complex, passive structures, it compromises user efficiency. Forcing an operator to interpret meaning constitutes a structural product failure, irrespective of user ability. True accessibility ensures immediate, deterministic comprehension for every user across the global operational ecosystem.

Automation Requires Deterministic Constraints

When development teams automate documentation retrieval from source code, the operational logic driving that text generation must incorporate STE rules as core parameters.

Automated language generators excel at producing fluent prose. However, without deterministic boundaries, these engines systematically introduce rhetorical padding, passive structures, and polysemous verbs. Filtering automated output through a controlled language framework like ASD-STE100 ensures that software documentation remains predictable, standardised, and immediately actionable.

For technical communicators and editors enforcing these standards, linguistic governance is not a pedantic exercise in word choice. It is a necessary mechanism to safeguard data integrity and minimise cognitive strain across the digital enterprise.